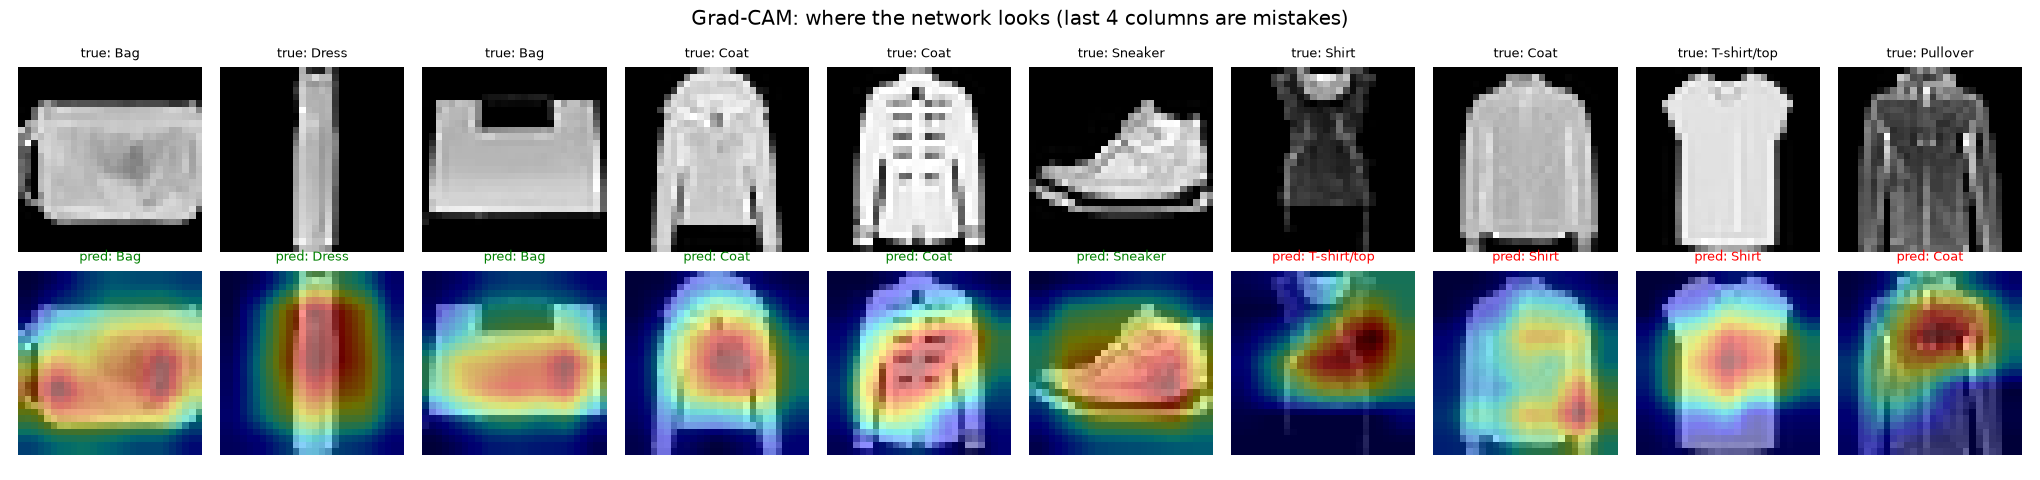
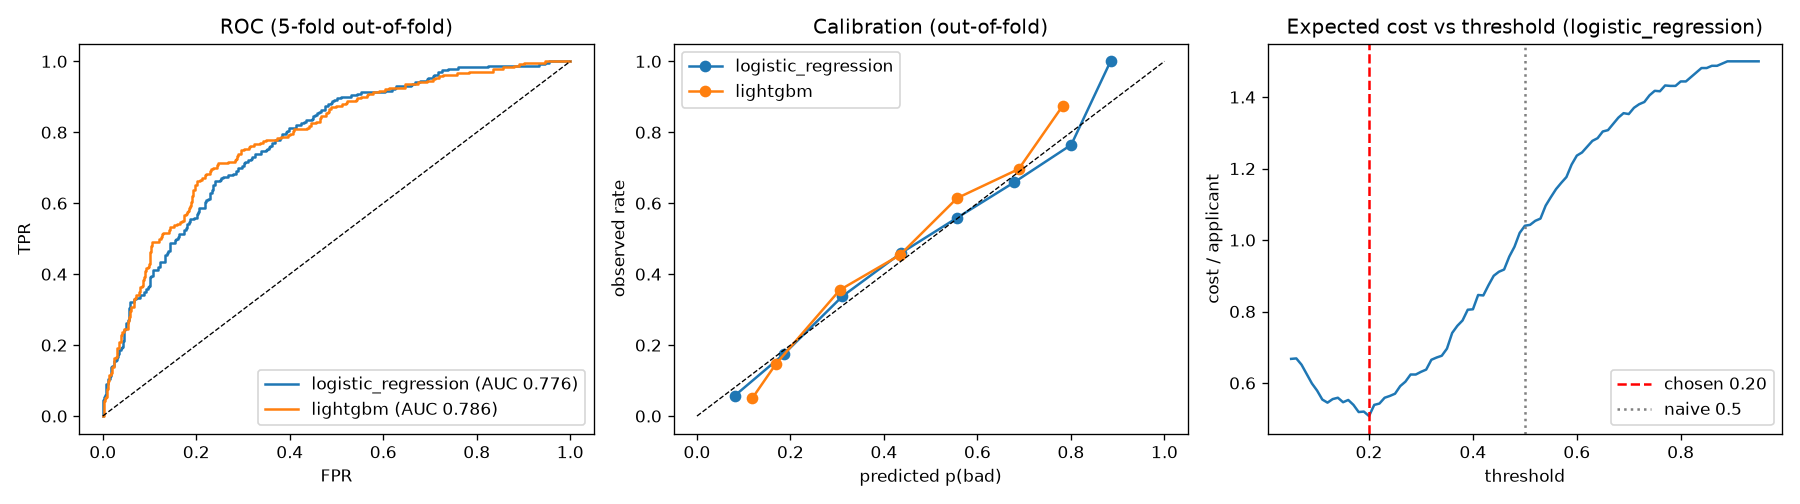
Each result below was measured on data the model never saw during training or tuning.
Hybrid retrieval + reranking QA
Answers questions over 2,067 Wikipedia passages and cites the passage it used. Each stage is benchmarked so every component has to earn its place.
Recall@1 0.74 → 0.88Recall@20 0.9978.3 F1 end-to-end
- BM25 written from scratch on a sparse term-document matrix
- Dense bi-encoder retrieval fused with BM25 by reciprocal rank fusion
- Cross-encoder reranking of the top 20, then a sliding-window extractive reader
- Loses only ~7 F1 versus a reader handed the gold passage
PyTorchTransformersSentence-TransformersSciPyInformation retrieval
question
├─► BM25 (from scratch) ─┐
│ ├─► rank fusion
└─► dense bi-encoder ────┘ │
▼
cross-encoder rerank (top 20)
│
▼
extractive reader (top 3)
│
▼
answer + source passage
Recall@1 BM25 .784 dense .636
fusion .740 + rerank .884
Mini-GPT from scratch
Decoder-only Transformer in PyTorch: causal multi-head attention, positional embeddings, AdamW with cosine decay, top-k sampling.
PyTorchTransformers
Code →
ML model serving API
Containerised inference service: FastAPI routing, Pydantic validation, health and metadata endpoints, pytest suite, Docker.
FastAPIDocker
Code →
Intern Tracker
Full-stack internship and hackathon discovery platform: Next.js frontend, FastAPI backend with passwordless OTP login, rate limiting, audit logging and admin tools, on PostgreSQL. API test suite and lint run in CI.
Next.jsFastAPIPostgreSQL
Code →
Stego food pre-ordering
Backend for a restaurant pre-order platform: Spring Boot 3 and Java 17, JWT access and refresh tokens, Stripe payments with signed webhooks, WebSocket order updates, Flyway migrations on PostgreSQL, integration tests in CI.
JavaSpring BootPostgreSQL
Code →